
学习Debian Tomcat日志管理最佳实践,能轻松解决哪些具体日志分析、优化和故障排查问题?
- 内容介绍
- 文章标签
- 相关推荐
• 硬盘空间被无效日志填满,导致程序宕机。• 日志文件碎片化,无法统一查询,排查慢。其实,• 缺乏实时告警,业务异常未及时发现。• 合规审计缺失,日志完整性难以保证。不过,• 手工清理成本高,易出错。说起来,
在 Debian 程序中。把 Tomcat 日志统一放到 /var/log/tomcat,并设置正确的属主属组,可让运维人员快速定位问题。
# mkdir -p /var/log/tomcat && chown tomcat:tomcat /var/log/tomcat
使用 logging.properties 控制日记级别:
# 在 conf/logging.properties 中添加
handlers= java.util.logging.FileHandler
java.util.logging.FileHandler.pattern = /var/log/tomcat/%t.log
java.util.logging.FileHandler.level = INFO
java.util.logging.FileHandler.formatter = java.util.logging.SimpleFormatter
通过 AccessLogValve 把访问日志集中管理:
统一目录 + 明确权限 + 标准化格式,让你在遇到报错时可以直接用 tail 或 grep 快速定位。
使用 logrotate 自动切割、压缩并删除旧日志。
# /etc/logrotate.d/tomcat
/var/log/tomcat/*.log {
daily
missingok
rotate 30
compress
delaycompress
notifempty
create 640 tomcat adm
}
手工清理脚本示例:
# clear_tomcat_log.sh
LOG_DIR=/var/log/tomcat
find $LOG_DIR -type f -mtime +30 -name '*.log' -delete
- 磁盘占满 → 自动清理;
- 旧日志冗余 → 压缩归档;
- 运维成本 ↓ → 定时任务自动执行。
- Error/Warn: 必须记录,用于业务异常检测;
- Info: 常规业务流程记录;
- Debug/Trace: 开发阶段使用,生产环境关闭。
AWS CloudWatch 或 Graylog 可接入实时监控:
# Example Logstash config to ship Tomcat logs to ELK Stack
input {
file {
path => "/var/log/tomcat/*.log"
start_position => "beginning"
sincedb_path => "/dev/null"
}
}
output {
elasticsearch { hosts => }
}
- Noisy logs 会淹没关键信息;说起来,
- Sift through logs becomes efficient when level is set correctly.
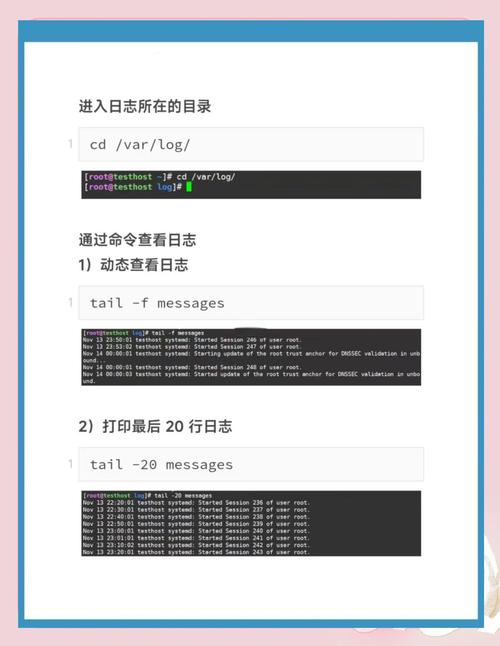
从实时监控实例来看。 使用 `tail` 与 `grep` 快速定位错误。
# Real‑time error view:
tail -f /var/log/tomcat/catalina.out | grep --color=auto ERROR
# Last week's error summary:
grep -i error /var/log/tomcat/*.log | wc -l
# Search specific exception:
grep 'NullPointerException' /var/log/tomcat/*.log | less
# Notify via Slack when an ERROR appears:
while true;do tail -n0 -F /var/log/tomcat/catalina.out | \
grep --line-buffered "ERROR" | \
xargs -I {} curl -X POST -H 'Content-type: application/json' \
-d '{"text":"Tomcat ERROR detected:
{}}"}' https://hooks.slack.com/services/...'
# add sleep if necessary to throttle notifications
done &&
告警设置小技巧:利用 `systemd` 的 `OnFailure=` 指令,当服务因异常停止时自动触发报警脚本。
# systemd unit snippet
ExecStart=/usr/bin/start-tomcatt.sh
Restart=on-failure
OnFailure=notify-slack@%N.service
# notify-slack@service template sends email or webhook on failure.
五、安全合规与归档策略
- Deny read/write access to non‑admin users via ACLs;
-
Easily audit changes with auditd rule:
`auditctl -w /var/log/tomcat/ -k tomcats-logs`
- CIS Benchmarks 建议保留至少30天的访问/错误日志,以满足合规要求。若需长期存储,可压缩后上传至对象存储。
六、故障排查实战案例
- - **502 Bad Gateway**:查看 catalina.out 是否有 “Connection reset by peer”;
-
- **OutOfMemoryError**:检查 heap dumps 并对 logback 配置 `
` 做适配; - - **Thread Dump**:在 `/opt/java/bin/jstack pid> thread_dump.txt` 后把结果上传至 Graylog,通过关键字检索 “waiting for monitor entry”。
至于示例,快速重启并验证配置是否生效:
# Force log rotation and reload TomCat configuration without downtime.
sudo logrotate --force /etc/logrotate.d/tomcat && sudo systemctl reload tomcatt.service
# Verify that new config is active by grepping pattern in catalina.out.
grep 'Started' /var/log/tomcat/catalina.out | tail –n1
# If no output → something went wrong,check service status.
systemctl status tomcatt.service | grep Active
# look for "active "
# if not running。review journalctl –u tomcatt.service for errors.
七、实用脚本集合
find /var/log/tomcats/*/.log -mtime +14 -delete
echo "Old logs cleared"
`
clear_access_logs.sh
每月将 access_log.* 移动到 archive/ 并压缩
`mkdir –pv archive/$ && mv access_log.* archive/$/ && tar czf archive/$/access_$.tar.gz archive/$`
monitor_errors.sh
持续监听错误并发送邮件提醒
`while true;do tail –n0 –F catalina.out | grep ERROR | mailx –s "TomCat Error Alert";done &,&怎么说呢,
`
从痛点到常用方法的闭环方法
-
A+结构化目录 + 标准化格式 → 快速定位;B+自动轮转 + 定期归档 → 防止磁盘爆满;按理说,C+细粒度级别控制 → 减少噪声;D+ELK/Grafana 集成 → 实时可视化告警;E+安全合规设计 → 满足审计需求。F+实战脚本 + 程序监控 → 持续保障业务稳定。怎么说呢,
<\/ul>"
• 硬盘空间被无效日志填满,导致程序宕机。• 日志文件碎片化,无法统一查询,排查慢。其实,• 缺乏实时告警,业务异常未及时发现。• 合规审计缺失,日志完整性难以保证。不过,• 手工清理成本高,易出错。说起来,
在 Debian 程序中。把 Tomcat 日志统一放到 /var/log/tomcat,并设置正确的属主属组,可让运维人员快速定位问题。
# mkdir -p /var/log/tomcat && chown tomcat:tomcat /var/log/tomcat
使用 logging.properties 控制日记级别:
# 在 conf/logging.properties 中添加
handlers= java.util.logging.FileHandler
java.util.logging.FileHandler.pattern = /var/log/tomcat/%t.log
java.util.logging.FileHandler.level = INFO
java.util.logging.FileHandler.formatter = java.util.logging.SimpleFormatter
通过 AccessLogValve 把访问日志集中管理:
统一目录 + 明确权限 + 标准化格式,让你在遇到报错时可以直接用 tail 或 grep 快速定位。
使用 logrotate 自动切割、压缩并删除旧日志。
# /etc/logrotate.d/tomcat
/var/log/tomcat/*.log {
daily
missingok
rotate 30
compress
delaycompress
notifempty
create 640 tomcat adm
}
手工清理脚本示例:
# clear_tomcat_log.sh
LOG_DIR=/var/log/tomcat
find $LOG_DIR -type f -mtime +30 -name '*.log' -delete
-
磁盘占满 → 自动清理;
-
旧日志冗余 → 压缩归档;
-
运维成本 ↓ → 定时任务自动执行。
-
Error/Warn: 必须记录,用于业务异常检测;
-
Info: 常规业务流程记录;
-
Debug/Trace: 开发阶段使用,生产环境关闭。
AWS CloudWatch 或 Graylog 可接入实时监控:
# Example Logstash config to ship Tomcat logs to ELK Stack
input {
file {
path => "/var/log/tomcat/*.log"
start_position => "beginning"
sincedb_path => "/dev/null"
}
}
output {
elasticsearch { hosts => }
}
-
Noisy logs 会淹没关键信息;说起来,
-
Sift through logs becomes efficient when level is set correctly.
从实时监控实例来看。
使用 `tail` 与 `grep` 快速定位错误。
# Real‑time error view:
tail -f /var/log/tomcat/catalina.out | grep --color=auto ERROR
# Last week's error summary:
grep -i error /var/log/tomcat/*.log | wc -l
# Search specific exception:
grep 'NullPointerException' /var/log/tomcat/*.log | less
# Notify via Slack when an ERROR appears:
while true;do tail -n0 -F /var/log/tomcat/catalina.out | \
grep --line-buffered "ERROR" | \
xargs -I {} curl -X POST -H 'Content-type: application/json' \
-d '{"text":"Tomcat ERROR detected:
{}}"}' https://hooks.slack.com/services/...'
# add sleep if necessary to throttle notifications
done &&
告警设置小技巧:利用 `systemd` 的 `OnFailure=` 指令,当服务因异常停止时自动触发报警脚本。
# systemd unit snippet
ExecStart=/usr/bin/start-tomcatt.sh
Restart=on-failure
OnFailure=notify-slack@%N.service
# notify-slack@service template sends email or webhook on failure.
五、安全合规与归档策略
-
Deny read/write access to non‑admin users via ACLs;
-
Easily audit changes with auditd rule:
`auditctl -w /var/log/tomcat/ -k tomcats-logs`
-
CIS Benchmarks 建议保留至少30天的访问/错误日志,以满足合规要求。若需长期存储,可压缩后上传至对象存储。
六、故障排查实战案例
-
- **502 Bad Gateway**:查看 catalina.out 是否有 “Connection reset by peer”;
-
- **OutOfMemoryError**:检查 heap dumps 并对 logback 配置 `
` 做适配;
-
- **Thread Dump**:在 `/opt/java/bin/jstack pid> thread_dump.txt` 后把结果上传至 Graylog,通过关键字检索 “waiting for monitor entry”。
至于示例,快速重启并验证配置是否生效:
# Force log rotation and reload TomCat configuration without downtime.
sudo logrotate --force /etc/logrotate.d/tomcat && sudo systemctl reload tomcatt.service
# Verify that new config is active by grepping pattern in catalina.out.
grep 'Started' /var/log/tomcat/catalina.out | tail –n1
# If no output → something went wrong,check service status.
systemctl status tomcatt.service | grep Active
# look for "active "
# if not running。review journalctl –u tomcatt.service for errors.
七、实用脚本集合
clearoldlogs.sh
删除14天前所有 *.log 文件
find /var/log/tomcats/*/.log -mtime +14 -delete
echo "Old logs cleared"
`
clear_access_logs.sh
每月将 access_log.* 移动到 archive/ 并压缩
`mkdir –pv archive/$ && mv access_log.* archive/$/ && tar czf archive/$/access_$.tar.gz archive/$`
monitor_errors.sh
持续监听错误并发送邮件提醒
`while true;do tail –n0 –F catalina.out | grep ERROR | mailx –s "TomCat Error Alert";done &,&怎么说呢,
`
从痛点到常用方法的闭环方法
-
A+结构化目录 + 标准化格式 → 快速定位;B+自动轮转 + 定期归档 → 防止磁盘爆满;按理说,C+细粒度级别控制 → 减少噪声;D+ELK/Grafana 集成 → 实时可视化告警;E+安全合规设计 → 满足审计需求。F+实战脚本 + 程序监控 → 持续保障业务稳定。怎么说呢,
<\/ul>"